
Reliability / Predictive maintenance
Predictive Maintenance AI: Monitoring and Controls
Predicting an equipment fault is not the same as proving one. The useful question is how a maintenance team decides which alerts deserve action and whether the model is still reliable.
Sections in this article
Use predictive maintenance alerts as evidence to investigate, not as automatic proof of failure. Track false alarms and missed faults, verify sensor health, record technician findings and keep established protection and maintenance procedures independent of the model.
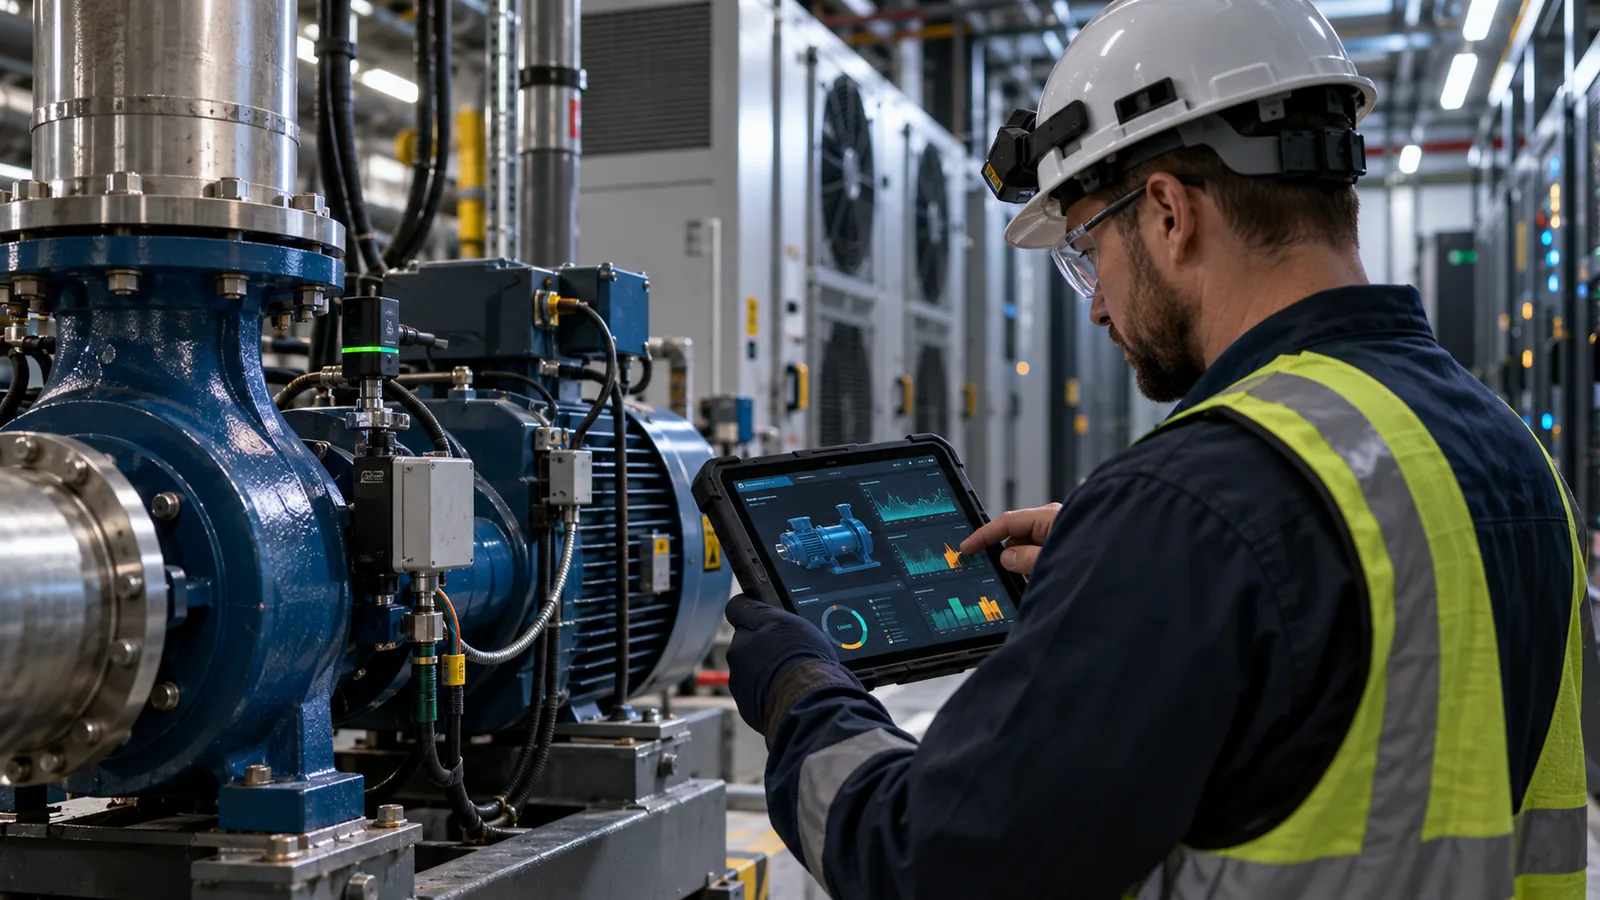
A UPS battery string, water pump, cooling fan or standby generator can generate condition-monitoring data before a visible failure occurs. AI-enabled predictive maintenance software can compare that data with historical patterns and flag changes that deserve inspection. Its value depends on the quality of those alerts, the remaining life of the component and the team's ability to act safely.
Predictive alerts should supplement approved preventive maintenance and condition-monitoring programs. A low model risk score is not a substitute for mandated testing, manufacturer recommendations or hardwired protection.
What information can a predictive model use?
| Equipment | Potential signals | What to verify |
|---|---|---|
| UPS and batteries | Test results, available battery monitoring data, temperatures and voltage trends. | Instrumentation quality, battery technology, test history and supplier guidance. |
| Pumps and fans | Vibration, current draw, pressure, flow and operating state. | Load conditions, mounting changes, calibration and mechanical inspection. |
| Generators | Starting behavior, temperatures, run hours and available engine diagnostics. | Exercise-test conditions, fuel maintenance and observed defects. |
| Cooling plant | Equipment alarms, power, temperatures and cycle history. | Whether conditions reflect a fault or normal seasonal operation. |
Not every facility has every sensor listed above. Claims about predictive lead times require representative validation data for the actual equipment population. A model cannot be assumed to predict a particular failure “weeks in advance” simply because its vendor offers machine learning.
False alarms and missed failures matter more than headline accuracy
When equipment failures are uncommon, a model can appear accurate by predicting “normal” almost all the time. Better measures distinguish alerts that correspond to real faults from faults that were not detected. Define the evaluation period and what counts as a confirmed failure before calculating these rates.
The model warns of a fault that inspection and follow-up do not substantiate. Costs include investigation time and alert fatigue.
The model does not warn before a relevant failure. Impact depends on redundancy, protection systems and response time.
These outcomes do not always have equal costs. A nuisance alert on a noncritical fan is different from a missed anomaly in a nonredundant critical component. Operators should define alert thresholds for each equipment class using reliability objectives, inspection capacity, consequences and the evidence available.
An illustrative alert-quality calculation
Imagine a review of 100 model alerts. Technicians substantiate 30 as actionable conditions; 70 are not confirmed. The precision over this set is 30 / 100 = 30%. This does not tell us recall, the missed-failure rate or whether the 70 alerts were truly wrong; establishing those requires tracking the wider equipment population over an agreed observation window.
Likewise, a low precision figure can sometimes be accepted for a catastrophic, inexpensive-to-check condition, while a high precision threshold may be appropriate for disruptive inspections. There is no universally optimal sensitivity setting.
Watch the model, the equipment and the sensors
Changes in the environment
Replacing a pump, changing its duty cycle or moving a fan can change normal vibration and current signatures. Data drift may be harmless, but it can also undermine predictions. Document changes to equipment and retrain or recalibrate the model only when evaluation demonstrates the need and the replacement version is validated.
Changes in data quality
A loose vibration sensor or an aging temperature probe can produce unusual measurements even when the asset remains healthy. Before accepting an alert, verify sensor integrity and whether the signal is physically plausible. Monitor missing data, stuck readings, communication gaps and calibration records alongside model performance.
Changes in the task
If teams begin using a monitoring model to authorize automatic shutdowns, the use case has fundamentally changed. It requires a fresh operational risk review and an approved control design; a monitoring model validated only to issue alerts cannot automatically be treated as a protective controller.
A technician-centered response workflow
- 01Triage the alert
Confirm equipment identity, severity, current operating state, redundancy and whether existing protection alarms also indicate a problem.
- 02Verify through approved methods
Use site-approved diagnostics, historical trends and competent inspection before authorizing intrusive work or parts replacement.
- 03Record the outcome
Link the alert to the maintenance ticket, findings, intervention, subsequent performance and whether the prediction was useful.
- 04Feedback and reassessment
Review patterns of missed faults, repeated nuisance alerts and any changes to data or equipment. Validate changes before deployment.
Make responsibility explicit
Facility engineering owns the decision to inspect, isolate or repair equipment. Reliability personnel define the metrics and investigate recurring errors. The model owner controls version changes, monitoring and supplier escalation. Security and IT teams manage connectivity and access to operational technology. This separation prevents a prediction score from silently becoming an operational order.
When an alert concerns a component with limited redundancy, follow the site's established reliability and safety plan. Do not automatically migrate computing workloads or switch power paths based on an AI alert unless those actions are separately engineered, authorized and tested.
The outcome to aim for is not the greatest possible number of predictions. It is more reliable maintenance decisions, with enough recorded evidence to tell when the model helps and when technicians should disregard it.
Sources and further reading
Primary frameworks and reference materials. Engineering decisions require site-specific validation; legal classifications require assessment of the actual use case.
- AI Risk Management Framework: Measure and ManageNIST AI Resource Center
- AI RMF PlaybookNIST
- Guide to Industrial Control Systems SecurityNIST SP 800-82 Rev. 3