
Liquid cooling / Reliability
Data Center Liquid Cooling Leak Detection: Sensors and Response
A leak alarm is only useful when operators know where it originated and which action is safe. Detection, isolation and recovery must be designed together.
Sections in this article
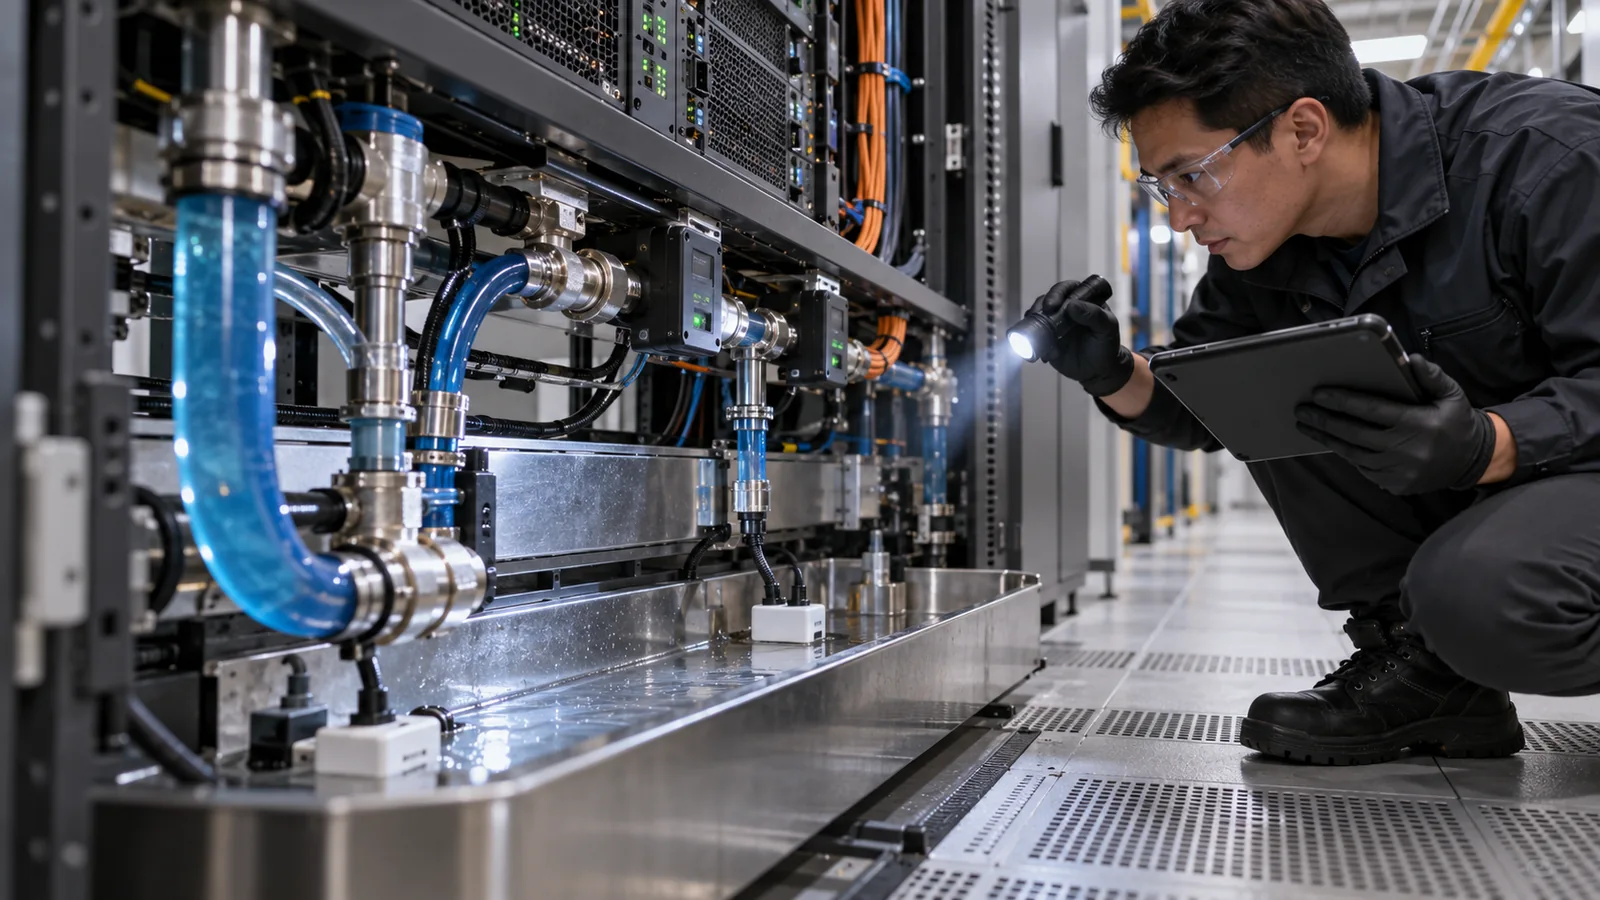
A drip tray sensor under a coolant distribution unit (CDU) has alarmed. The rack temperatures still look normal. Should the operator stop the secondary pump, close a manifold valve, or simply send someone to inspect the area? There is no safe universal response: an abrupt pump stop might protect against fluid loss but remove necessary cooling from healthy racks.
The useful design outcome is a location-aware alarm and isolation plan that an on-call engineer can follow. Leak detection is a combined mechanical, controls and IT problem, not a sensor-shopping exercise.
Map leak paths before selecting sensors
Draw the route from facility-side supply through the CDU, technology cooling system (TCS), row headers, rack manifolds, quick disconnects and server cold plates. Identify where a small leak would collect, how it could move through the rack and whether liquid may reach electrical components. The answer depends on hose routing, containment, trays and cabinet design.
Not every component needs identical detection. A slow drip beneath a connector requires different coverage from a ruptured main header. Use a failure-modes review to rank consequences, credible leak rates, containment volume and whether a particular sensor can detect the fluid actually used.
Which detector fits which location?
| Detection method | Good application | Blind spot to test |
|---|---|---|
| Conductive sensing cable | Drip trays and exposed manifolds with compatible conductive liquid | Some low-conductivity or dielectric fluids may not trigger it |
| Spot detector or film | Rack base, connector shelf and a known drip point | Leaks falling outside the small sensing area |
| Liquid level or tray sensor | Bunds and contained areas | May report only after a significant fluid volume accumulates |
| Pressure / supply-return flow trend | System-wide major leak detection and secondary confirmation | Noise, thermal expansion and sensor calibration affect sensitivity |
| Visual / operator inspection | Verification and repair assessment | Cannot substitute for timely unattended alarming |
Distance-locating sensing cables can narrow a fault to a section of cable, but the precision depends on product and installation. Do not assume every rope sensor identifies the exact rack. For a liquid with special dielectric or chemical characteristics, request a wet test with that actual fluid rather than relying on a generic water demonstration.
The OCP Leak Detection and Intervention white paper is a useful reference for assessing liquid-cooled IT deployments. Combine such guidance with hardware-vendor requirements, site fire/electrical safety rules and approved emergency procedures.
Alert, verify and contain without making the failure worse
Separate immediate emergency conditions from a low-consequence warning. A suspected leak onto energized electrical equipment demands a different response than moisture within a fully contained CDU tray. The control strategy should define priorities, affected zones, and which actions are independently verified before going into production.
Report sensor identity, location, fluid loop, timestamp and severity to the staffed control point.
Use available telemetry and safe observation; follow electrical exclusion rules if liquid may have reached energized equipment.
Use only approved valve/pump sequences that preserve required cooling for other loads. Emergency shutoff behavior is site-specific.
Where supported, notify workload owners of threatened racks and use prevalidated workload protection or shutdown procedures.
A critical distinction: automatic global pump shutdown is not always safe. Without an engineered bypass or independent cooling path, isolating one leak may interrupt an entire cooling loop. An automated migration of a distributed training job also may not be feasible in the available thermal window. Those dependencies must be tested during commissioning.
There is no universal 500 ms alarm-validation rule or 2-second valve closure requirement. The correct acceptance limits follow the measured detector, communications and actuator capabilities, plus the equipment's failure response time and an engineering safety assessment.
A practical field response for one rack leak
Assume, as an illustrative exercise, that a rack-base spot detector operates after a service intervention. The control room first validates the rack identity and checks the configured severity. The technician does not reach inside potentially energized wet equipment to investigate. The incident leader follows electrical isolation rules, confirms the approved cooling-zone isolation steps and records the initial alarm and equipment state.
Record equipment IDs, detector ID, time, and possible liquid exposure.
Authorized personnel execute the documented safe isolation sequence.
Specialists locate the failure, replace approved components and assess affected IT.
Retest leak-tightness, flow, sensors and the alarm chain before return to duty.
Fluid cleanup and any draining, purging or electrical restoration must be performed under manufacturer and site procedures by qualified teams. A universal recommendation to use wet vacuums, nitrogen purges or chemical treatment around live IT would be unsafe. If the spill may have reached electrical equipment, electrical safety protocols take precedence.
What counts as a passed leak-detection test?
During FAT/SAT/IST, require a test that exercises the entire intended chain, not just a green sensor light: compatible test liquid or approved simulation, controller input, time-stamped alarm, correct rack identity, expected isolation state, operator notification and safe reset. Keep a record of any false alerts or sensor failures.
Sensor: LDK-R12-04 · Zone: Rack 12 lower shelf · Test fluid: approved loop coolant · Expected: local + central alarm, correct location, approved branch isolation · Result: measured timestamps and deviations, not an assumed response time.
Before scaling: verify that someone on every shift can find the fault, identify which racks share the coolant branch and access the controlled return-to-service procedure without improvisation.
Sources and further reading
Primary frameworks and reference materials. Engineering decisions require site-specific validation; legal classifications require assessment of the actual use case.
- OCP Leak Detection and Intervention white paperOpen Compute Project
- OCP cold-plate ecosystem and fluid connectionsOpen Compute Project
- NIST guidance on operational technology reliability and safetyNIST